Testing AI-powered applications is fundamentally different from testing traditional software.
The UI can change frequently. The output can vary. The exact path through the application may not even be known until runtime. But most browser automation frameworks still assume the opposite: a fixed sequence of interactions that will execute the same way every time.
AI Action was Momentic's response to this problem back in our YC W24 days. The idea was simple: instead of scripting every click, describe a goal and let an agent figure out how to achieve it.
In practice, making that idea work at scale turned out to be much harder than it sounded.
Over the last two years we've built several versions of AI Action. Some prioritized replayability and determinism. Others prioritized adaptability. Each solved real problems, but each exposed new tradeoffs.
AI Action v3 is the result of those lessons. It combines replay, planning, and self-healing into a single architecture that allows tests to remain fast, deterministic, and resilient to application changes.
AI Action v1 and v2: Control Loops
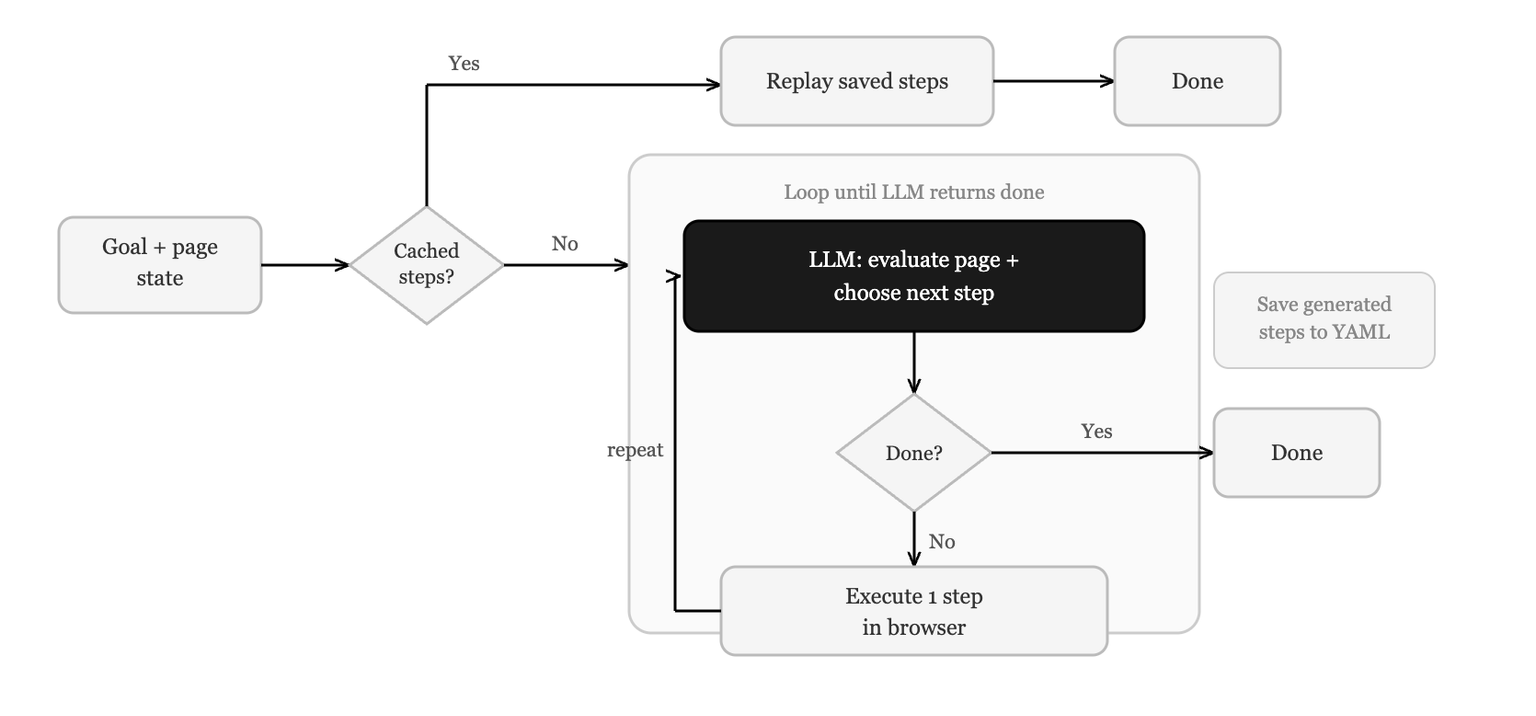
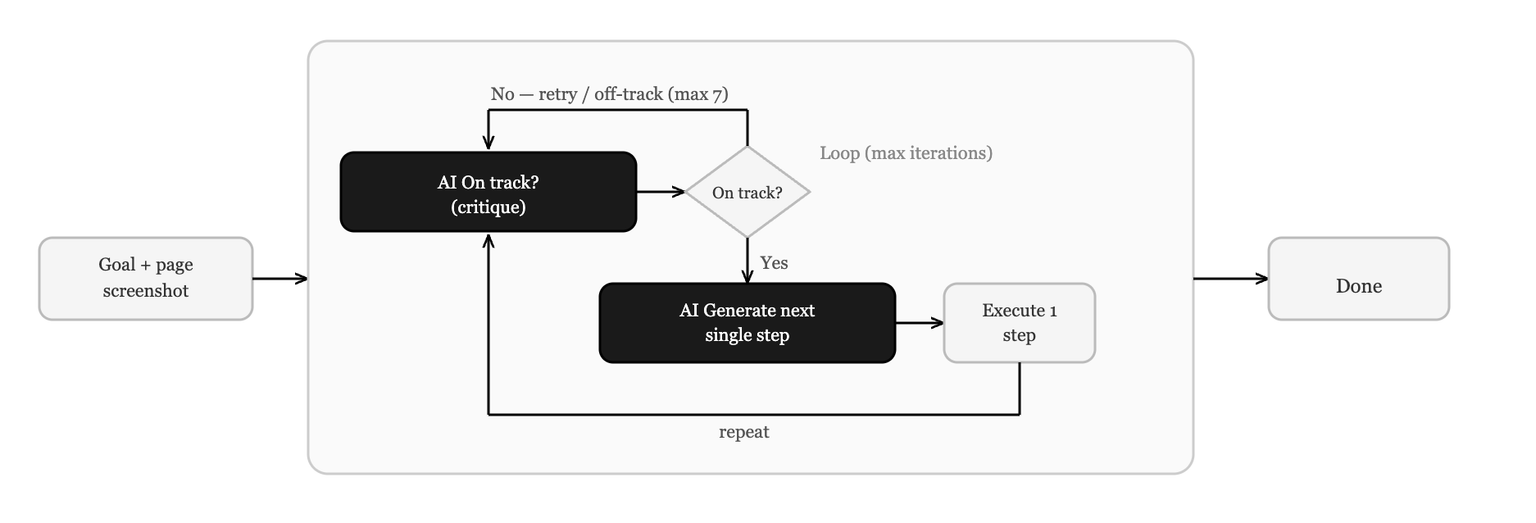
The previous implementations of AI Action were control loops: they repeatedly evaluated the current browser state and produced a single step toward the goal. The first two versions of AI Action were variations on this:
- v1: Generated one command at a time. On each turn, the model checked whether the goal was completed and returned either
SUCCESSor the next browser command. Momentic executed that command and persisted the sequence back into the test YAML. Replays were fast, but the cache lived in source control, which meant noisy diffs, brittle merges, and no clean CI recovery when a saved sequence broke.
- v2: Removed that cache entirely. Every run was fully dynamic: one LLM call critiqued progress and a second chose the next command. This kept YAML clean and avoided stale saved steps, but each run paid the full LLM cost again, which made runs slower, more expensive, and less deterministic.
The tradeoff
At first glance these seem like very different architectures. In reality, they were both attempts to balance the same tradeoff.
v1 prioritized replayability. Once a successful trajectory had been discovered, future executions could replay it cheaply and deterministically. The problem was that the trajectory lived in source control and could not repair itself when reality changed.
v2 prioritized adaptability. By planning from scratch on every run, it avoided stale trajectories entirely and adapted naturally to changing applications. The problem was that it sacrificed many of the performance and determinism benefits that replay provided.
Looking back, the tradeoff between the two versions was surprisingly simple:
| v1 | v2 | |
|---|---|---|
| Fast replay | ✅ | ❌ |
| Deterministic execution | ✅ | ❌ |
| Adapts to UI changes | ❌ | ✅ |
The lesson wasn't that caching was wrong. The lesson was that we needed a better place to put the cache.
Replay made execution fast and predictable. Planning made execution adaptable. The challenge was finding a way to get both.
This realization combined with new step caching infrastructure (described in our caching series ) ultimately led us to AI Action v3.
AI Action v3: Execute → Replay → Heal
AI Action v3 combines the strengths of both previous approaches.Like v2, it can dynamically discover how to accomplish a goal and adapt when applications change. Like v1, it can replay previously discovered trajectories quickly and deterministically. The difference is that trajectories are no longer stored in source control, and the system is capable of maintaining them automatically over time.The key architectural change is that planning and execution are no longer treated as the same problem.In v2, every execution required online planning. The system repeatedly examined the current browser state and asked an LLM what to do next. In v3, planning is used to discover and repair trajectories, while normal execution relies on replay.Conceptually, the lifecycle now looks like this:
- Execute: Use a tool-based agent to reach the desired goal and build a replayable trajectory.
- Replay: Reuse that trajectory on future runs without involving the agent.
- Heal: If replay can no longer reach the desired end state, reintroduce the agent to repair the failing step, then persist the new trajectory so future runs can replay successfully.
This allows AI Action to preserve the adaptability of v2 while recovering many of the speed and determinism benefits that made v1 attractive.
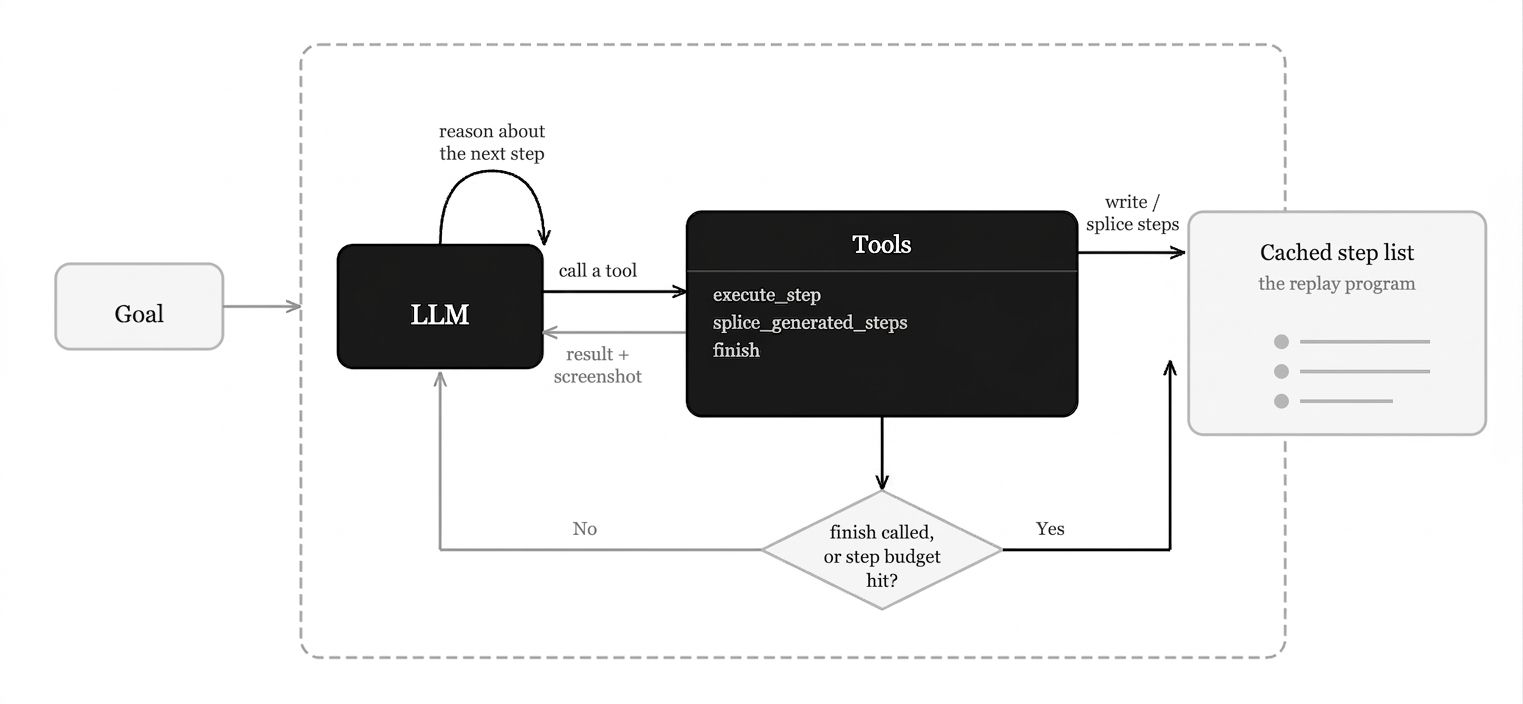
The agent itself is intentionally simple. Rather than exposing low-level browser automation APIs directly, we give it three crucial tools:
execute_stepsplice_generated_stepsfinish
execute_step gives the LLM the ability to manipulate the browser. It does this by generating CLI-like commands which then get translated into Momentic steps. For example, a single execute_step call’s input might look like:
{
  "steps": [
    "--step-type CLICK --description \"the destination field labeled Where to\"",
    "--step-type TYPE --description \"the destination input\" --value \"Dulles\"",
    "--step-type CLICK --description \"the Washington Dulles option in the destination suggestions\""
  ]
}
```
These commands are translated into the same Momentic steps that power every step within Momentic. This interface also helps avoid polluting the agent’s context window with browser interaction implementation details and helps it focus on the goal at hand.
Once these steps are executed by the subagent, they return the result, as well as a cache for that step. For example:
{
  "step": "--step-type CLICK ... --cache-id db9a8895...",
  "result": {
    "status": "SUCCESS",
    "cache": {
      "target": {
        "role": "combobox",
        "name": "Where to?"
      }
    }
  }
}
Notice the step result now has a --cache-id. These cache ids refer to the step cache row stored in Clickhouse, part of our new step caching infrastructure. These cache ids can be re-used on replay to avoid having the subagents have to use AI again.
Once the main AI Action agent has determined that it has achieved its goal it will then use the splice_generated_steps tool to assemble a replayable trajectory that can be replayed on the next run. For example, a call to the tool might look like:
{
  "steps": [
    "--step-type CLICK --description \"the trip type dropdown showing Round trip\" --cache-id d7546922-5cb1-484c-b50c-7acde472231f",
    "--step-type CLICK --description \"the One way option in the trip type menu\" --cache-id 221156b6-66c9-4993-bbbc-41589c50471b",
    "--step-type CLICK --description \"the destination field labeled Where to\" --cache-id db9a8895-69a6-419e-9d7f-990a7f9b234f",
  ],
  "startIndex": 0,
  "deleteCount": 0,
}
This trajectory is then also stored in Clickhouse as a part of this AI Action’s step cache.
Finally, once the model is confident that it has achieved the desired end state, it will call the finish tool with an input like:
{
  "success": true,
  "message": "Completed the Google Flights search for a one-way trip from San Francisco (SFO) to Washington Dulles (IAD) on July 4 and loaded the results page.",
  "autoGeneratedPostcondition" : "the Google Flights results page is displayed for a one-way trip from San Francisco to Washington Dulles on July 4"
}
In addition to marking the execution as complete, the < finish > tool generates a postcondition describing the expected end state. Future replays must satisfy this postcondition in order to be considered successful.This postcondition acts as a guardrail for replay. A trajectory may need to be repaired either because a replay step fails or because the replayed trajectory no longer reaches the desired end state.
When Replay Fails
But what happens when replay breaks?Suppose Google Flights ships a UI redesign and one of the cached steps can no longer be executed successfully. In a traditional Playwright or Selenium test, the run would fail and a human would need to update the implementation manually.
But with AI Action, when replay can no longer satisfy the desired postcondition, the system reintroduces the same agent used during the initial execute phase and the agent receives two tasks:
- Get the browser to the desired state.
- Update the stored trajectory so future executions can replay successfully again.
The v3 lifecycle looks like this:
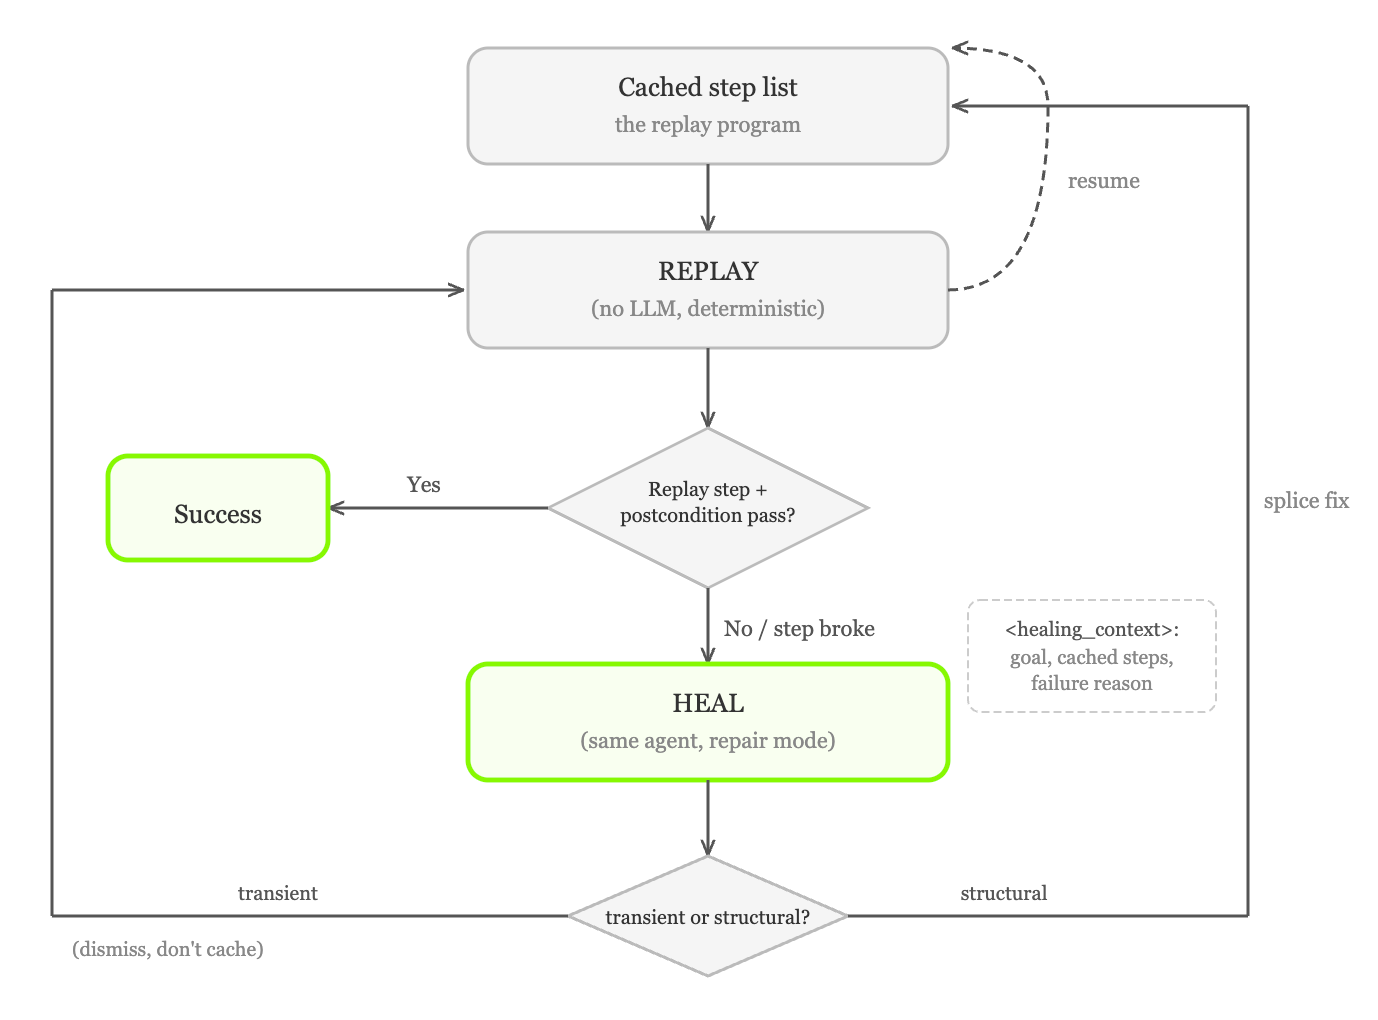
Replay → heal. Later runs replay with no LLM call, and only re-enter the agentic loop when a step breaks.
For a temporary pop-up, the healing agent can call the execute_step tool to close out the pop-up, and then resume executing the saved trajectory, which includes cache and thus will be fast.
For a UI overhaul, the healing agent can get the browser to the goal state like it did before by calling execute_step, and can edit the trajectory using the splice_generated_steps tool.
The crucial thing to note here is that the AI Action can maintain its own trajectory without having to modify the user’s test in source control. This is because the inputs are high-level goals, not granular steps like click or type. It enables the AI Action agent to adapt to a wide range of UX changes.
This paradigm shift is akin to imperative versus declarative programming (e.g. jQuery vs React). Now instead of defining the implementation, you just define your goal of what you want to achieve and the test will maintain itself. Notably this also simplifies test files. For example, for our Google Flights case, the test becomes much simpler, e.g.
Before:
steps:
- click: the trip type dropdown showing Round trip
- click: the One way option in the trip type menu
- click: the destination field labeled Where to
- type:
into: the destination input
text: Dulles
- click: the Washington Dulles option in the destination suggestions
- click: the Departure date field
- click: July 4 in the date picker calendar
- click: the Search button
- click: the blue Search button below the flight fields
After:
steps:
- act:
goal: search for flights from sfo to dulles for the day july 4, one way
This also has the added benefit of highlighting the intent of the test as opposed to just a list of individual browser interactions.
What’s next
AI Action v3 addresses the major limitations we encountered in earlier versions by separating trajectory discovery from trajectory execution.
Rather than asking an LLM what to do on every run, AI Action now uses an agent to discover a replayable trajectory once and stores that trajectory independently from the user's test. Subsequent executions replay the cached trajectory directly, avoiding the repeated model calls and online planning that made earlier approaches slower, more expensive, and less deterministic.
When reality diverges from the stored trajectory, whether due to a transient popup or a significant UI redesign, the agent is reintroduced to repair the trajectory and restore the desired end state. Once repaired, future executions return to replay mode.
The result is a system that preserves the adaptability of browser agents while achieving much of the speed, determinism, and operational simplicity traditionally associated with scripted automation.
This combined with the recent development of the simplified format (more to come on that in this month’s launch), leads us to believe that Momentic tests can soon start looking more like a series of user flows written in English, and less like a prescriptive series of steps to be executed.
If this kind of problem interests you: connect with us on LinkedIn , X , or check out our open opportunities at momentic.ai .